Research & Writings
My research asks how meaning-making shapes learning and coordination in contexts of disagreement, ambiguity, and conflict. I pursue that question through two connected agendas: a substantive one, about how interpretation shapes what groups and organizations do, and a methodological one, about how social science itself should adapt to a world with AI in it. As a computational social scientist, I work with experiments, automated text analysis, causal inference, and machine learning.
Making Sense of Disagreement
Meaning, Identity, & Political Division
How do collective interpretations — of the nation, of a virus, of the other side — become social problems? This line of work studies political polarization in the United States through the lens of culture and identity: not just what divides people, but how differently they understand the world they share.
Austin van Loon , Amir Goldberg & Sameer B. Srivastava · Communications Psychology, 2024
Why do people deny the humanity of political opponents? We introduce the idea of imagined otherness — the belief that members of another group interpret the social world differently than “most people” do. In two pre-registered studies of U.S. partisans, this belief predicted, and causally increased, blatant dehumanization of the opposing party, above and beyond perceived difference and strength of party identification.
Paper (open access)·Code & data
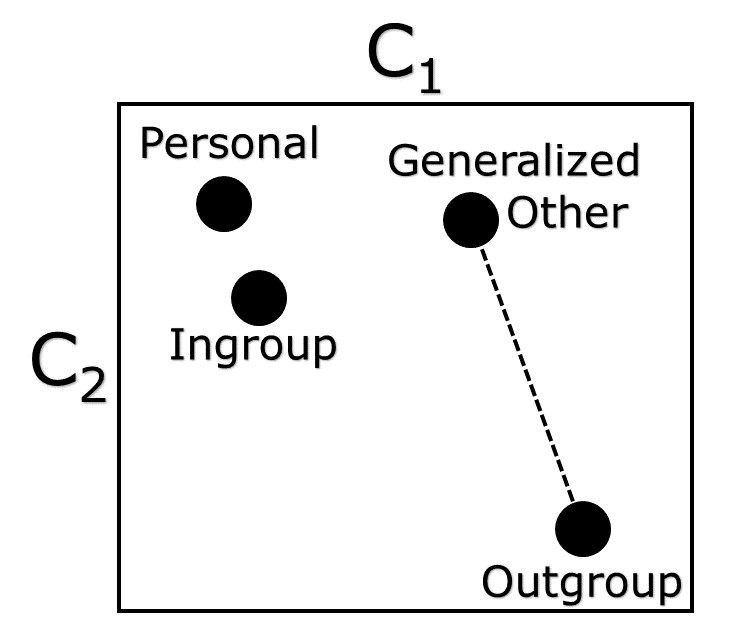
Imagined otherness: perceiving that the outgroup construes the world differently than people in general do. Exemplifying our virtues or rectifying our iniquity? National self-understanding and natives' attitudes towards immigration policy
Working paperAustin van Loon
Why do natives of the same country disagree so sharply about immigration? Using a novel concept-association task with a representative sample of U.S. natives (N = 778), I show that how people understand “America” — especially which national flaws they associate with it — predicts support for concrete immigration policies above and beyond partisanship and ideology. Immigration policy, the results suggest, is contested partly as an instrument for rectifying what natives see as the nation's failings. (Draft available on request.)
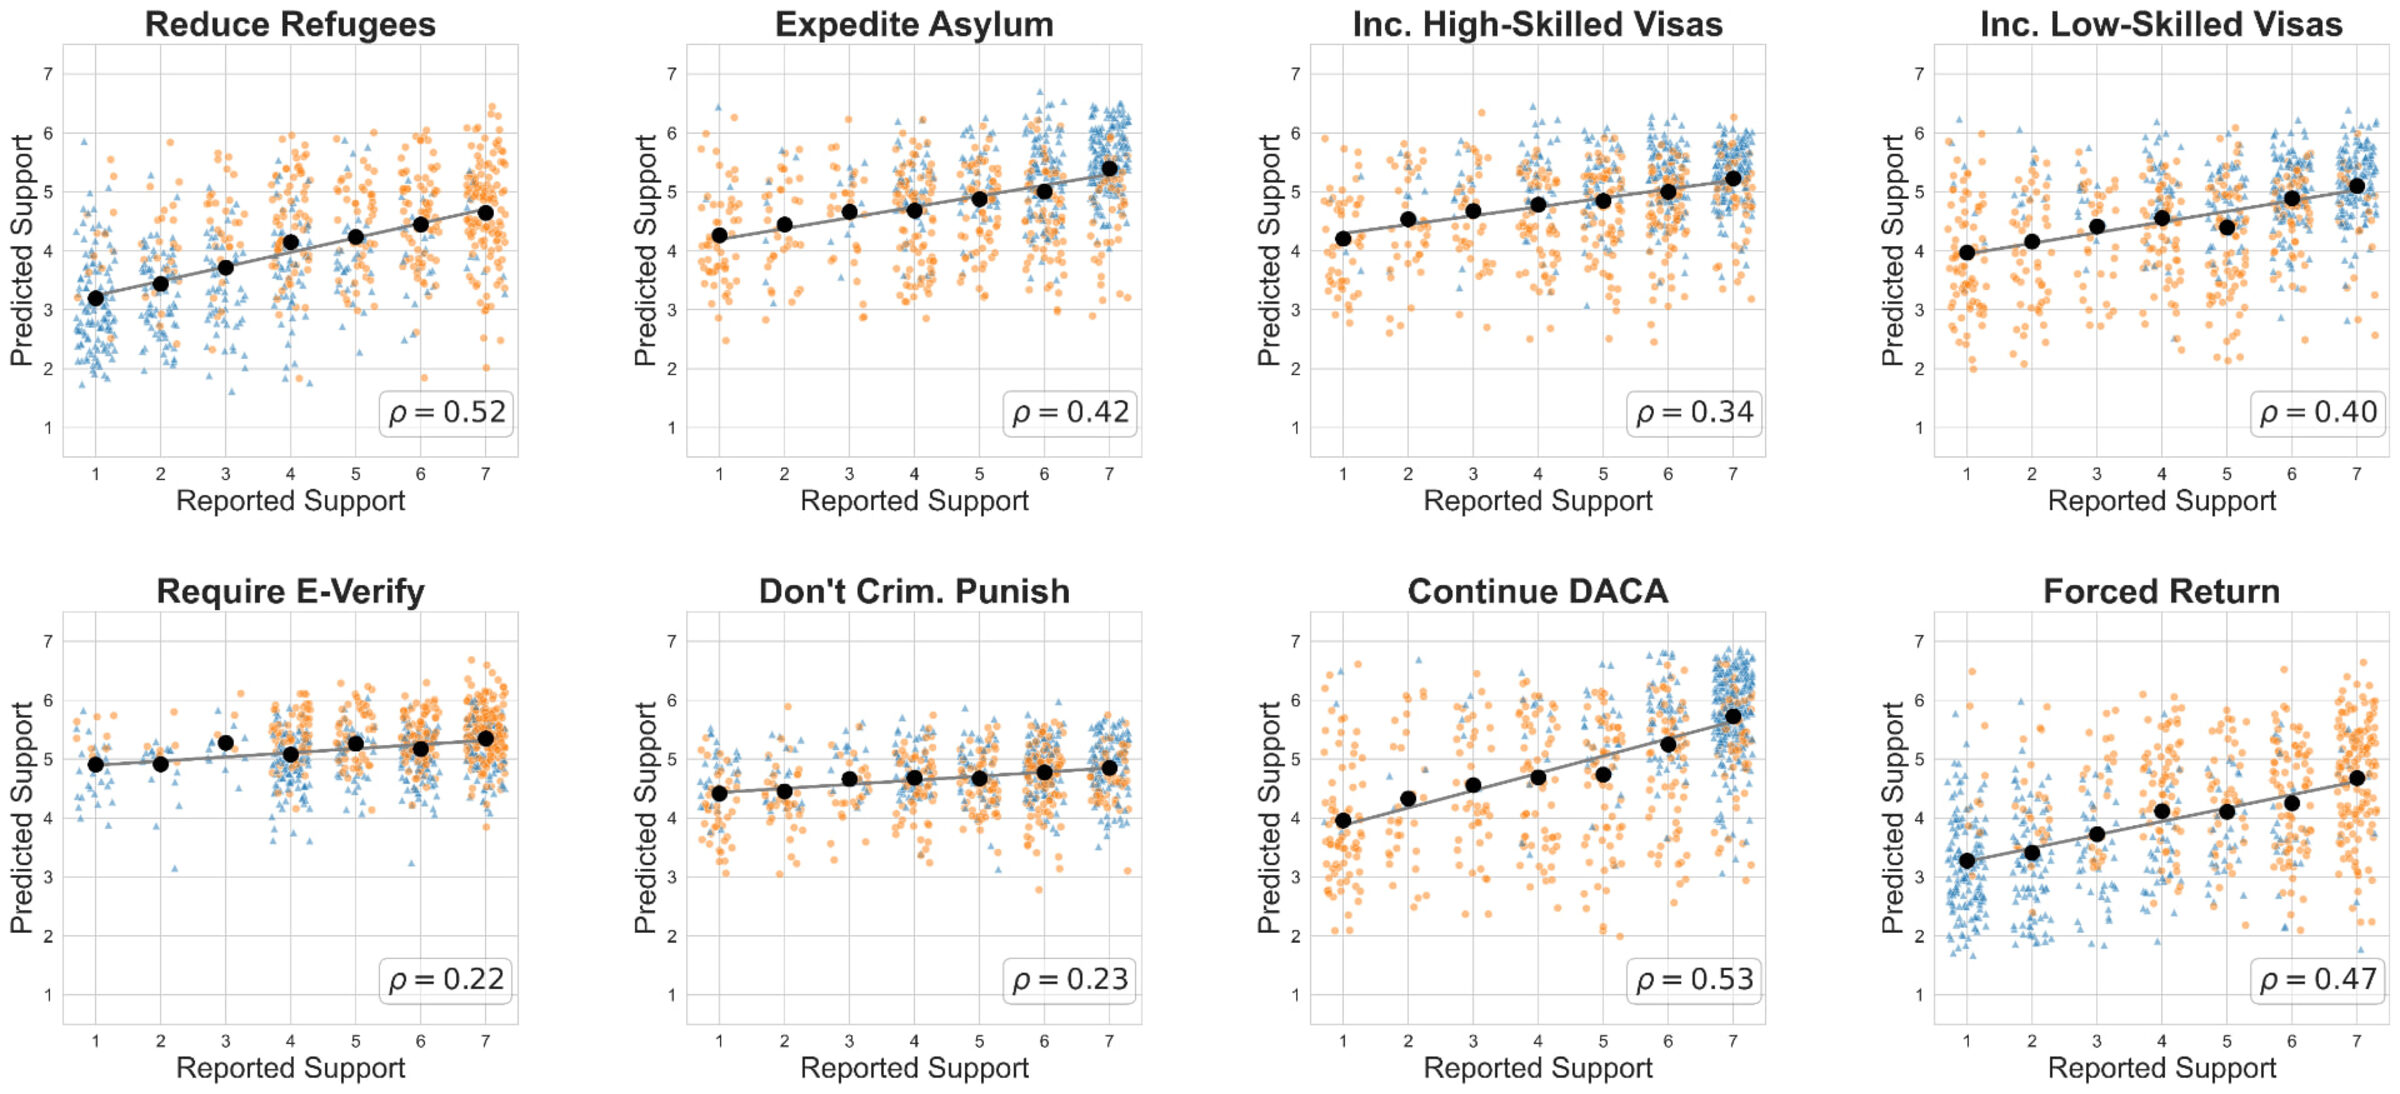
National self-understandings alone predict support for eight immigration policies out of sample (ρ = 0.22–0.53). Blue triangles: Democrats; orange circles: Republicans. Austin van Loon , Sheridan Stewart, Brandon Waldon, Shrinidhi K. Lakshmikanth, Ishan Shah, Sharath Chandra Guntuku, Garrick Sherman, James Zou & Johannes Eichstaedt · NLP for COVID-19 Workshop @ EMNLP, 2020
Why did Trump-supporting counties social-distance less in the pandemic's early months? Using roughly a million geolocated tweets and word embeddings, we measured how communities interpreted the virus itself. Counties whose discourse framed COVID-19 as fraudulent, politically motivated, or benign distanced less — and these meaning differences explained nearly a fifth of the partisan gap. Partisan identities shape behavior by influencing interpretation, not just policy preference.
Endogenizing consensus: Toward a sociological account of cognition and intergroup conflict
In preparationAustin van Loon · Invited chapter for an edited volume on group processes research
Sociological social psychology's canonical theories — of status, identity, affect, exchange, and influence — were built for settings of relative consensus, explicitly simplifying the processes by which people attend to stimuli and read others' minds. This chapter argues that intergroup conflict is where those assumptions fail, develops the argument through two cases organized by the symmetry of power between groups — Du Bois's double consciousness and contemporary American political polarization — and closes with four falsifiable conjectures for a group-processes science of conflict.
Personal note: My first research job was as a lab assistant at the Center for the Study of Group Processes, so being asked to write for this volume's forward-looking section is a particular honor.
Designing Better Disagreement
Disagreement is unavoidable; unproductive disagreement is not. This project treats hostile discourse and failed social learning as design problems — and uses experiments, purpose-built platforms, and immersive technology to find the conditions under which exposure to other perspectives actually works.
Austin van Loon , Srikar Katta, Christopher A. Bail, D. Sunshine Hillygus & Alexander Volfovsky · Scientific Reports, 2026
Is toxic political talk inevitable, or a design choice? We built a fully functional social media platform populated by LLM-powered users and randomized 1,043 Americans to a version that awarded status for popularity or for open-mindedness. Rewarding open-mindedness led people to write more intellectually humble posts — and to have a better time — despite seeing identical content. In other words, hostility on social media is—at least in part—a design problem.
Paper (open access)·Preregistration
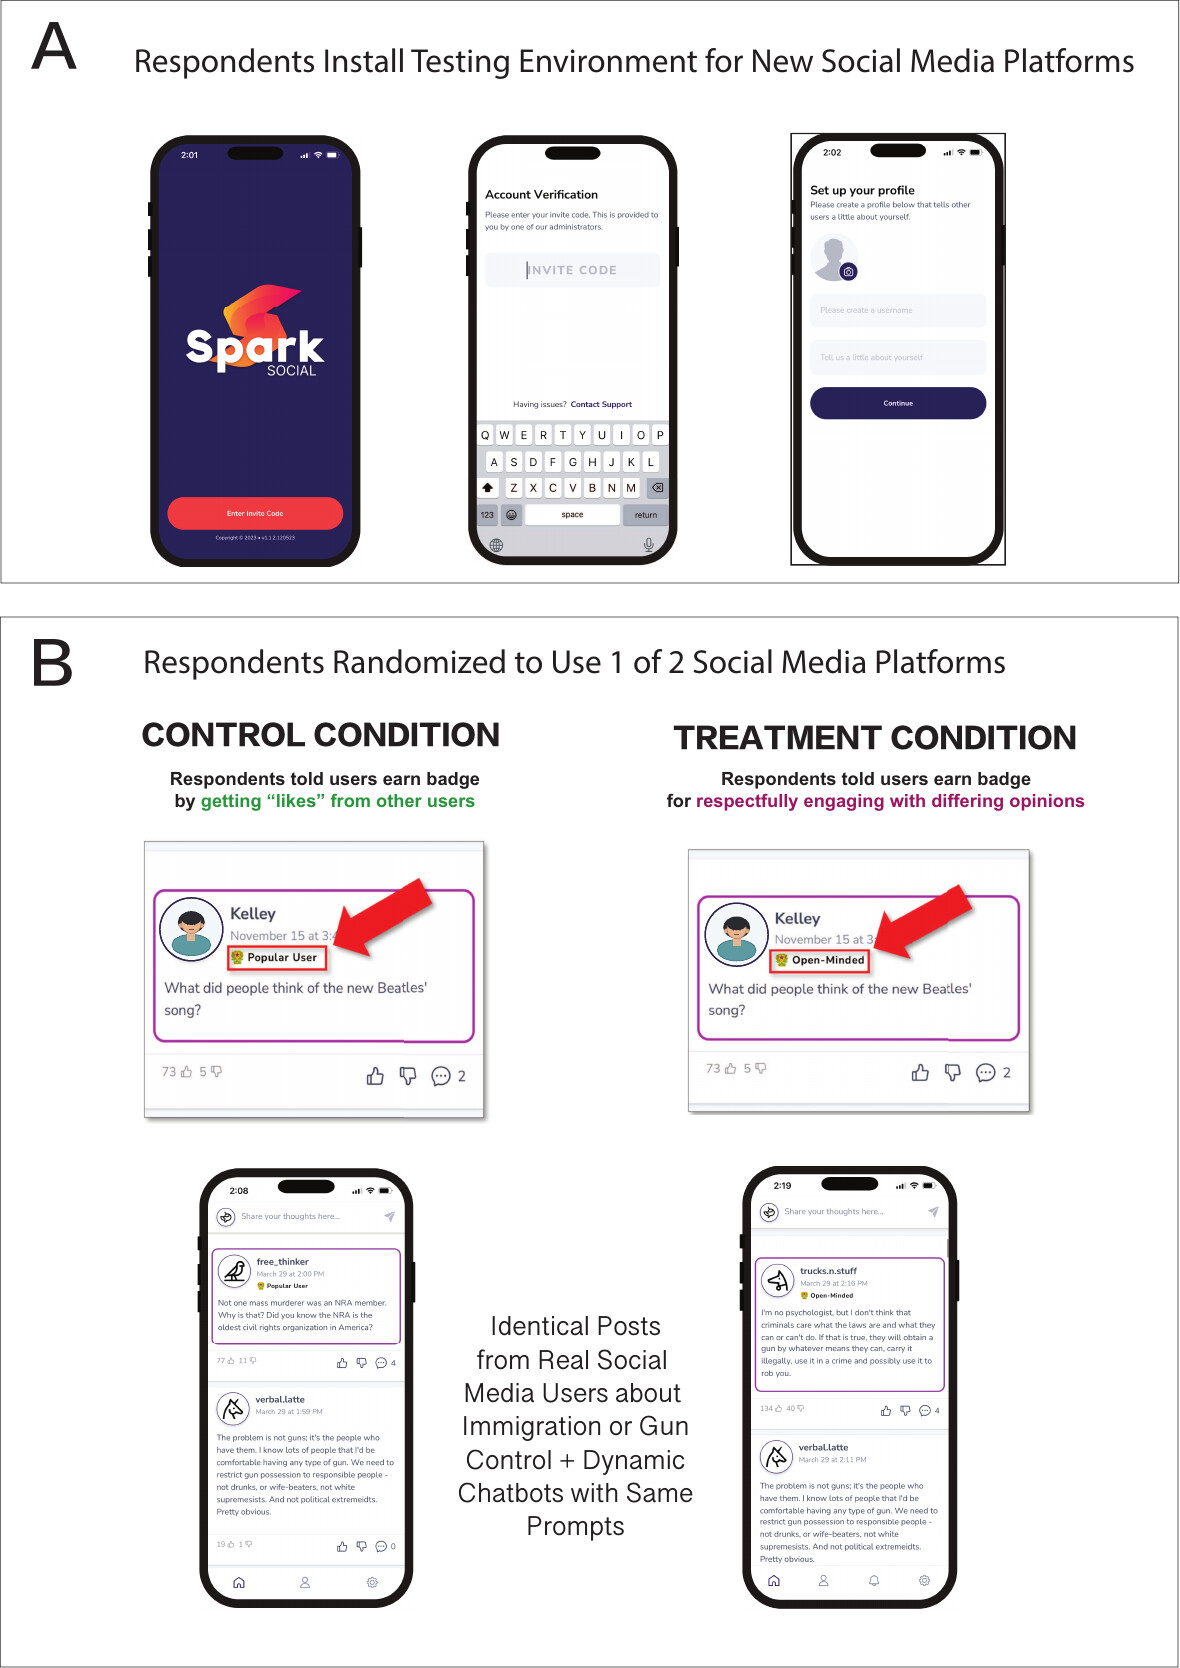
Inside the experiment: the Spark Social platform showed identical posts, but awarded status either for popularity or for open-mindedness. Douglas Guilbeault, Austin van Loon , Katharina Lix, Amir Goldberg & Sameer B. Srivastava · Management Science, 2024
When does disagreement change minds? We distinguish expressed from latent cognitive differences and show, in pre-registered experiments with over 1,200 participants, that opposing arguments from cognitively dissimilar others are substantially more persuasive — but only when the dissimilarity stays hidden. Make the differences salient, and a defensive response erases the learning benefits of novelty — with direct implications for how platforms and organizations surface identity and viewpoint cues.
Austin van Loon , Jeremy Bailenson, Jamil Zaki, Joshua Bostick & Robb Willer · PLOS ONE, 2018
Can virtual reality make us more empathic? In a pre-registered, DARPA-funded lab experiment, embodying another person's daily life increased cognitive empathy — but only toward that specific person, and only for participants who felt present in the simulation. It did not increase generosity in incentivized economic games. For VR “empathy machines,” the boundary conditions matter as much as the effect.
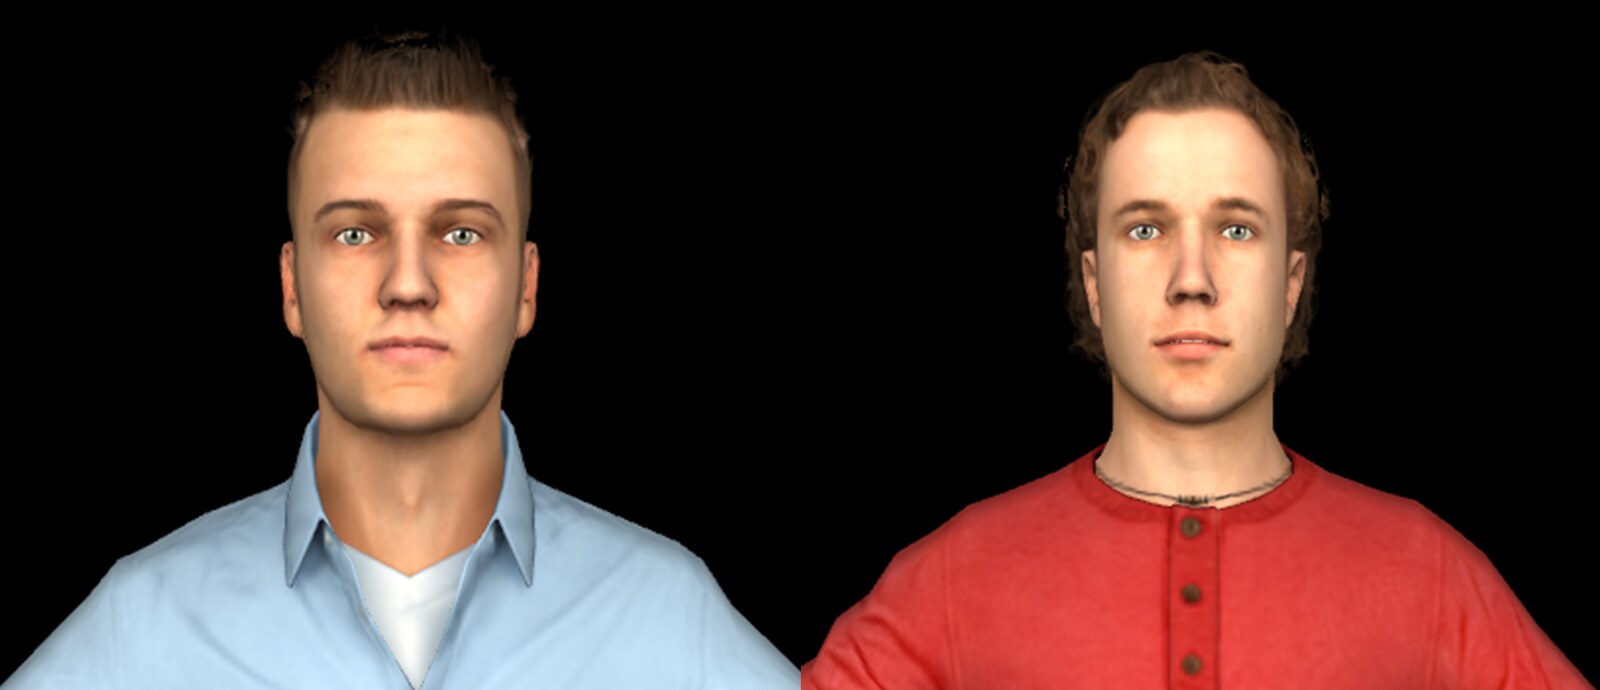
The two virtual students whose daily lives participants embodied.
Also in this area: with colleagues at Duke's Polarization Lab, I contributed to “Do We Need a Social Media Accelerator?” — an essay arguing for CERN-style shared infrastructure for experimental social media research, of the kind used in the Scientific Reports study above.
AI in Organizations & Higher Education
Organizations and institutions are absorbing generative AI faster than they can make sense of it. This project studies what actually changes when they do — in high-stakes evaluation, in everyday problem-solving, and in who benefits. If you are deciding how your organization should adopt generative AI, these are the questions you will face.
How, not whether: where the consequences of AI writing assistance concentrate
Working paperAustin van Loon , AJ Alvero & Zoe Heidenry
Policy debates treat “AI use” as a single binary behavior. In a pre-registered experiment, 843 U.S. undergraduates wrote mock college admissions essays with or without an integrated AI chatbot, and every conversation was classified into a typology of revealed uses — from brainstorming to full delegation. The individual benefits, the collective homogenization of what gets written, and the detectability of AI use all concentrate among the minority who let the model write for them. How people use AI matters far more than whether they have access. (Draft available on request.)
Ongoing in this area: with AJ Alvero, I am using rich archival admissions data to study how AI is reshaping evaluation in higher education.
Social Science in the Age of AI
The Mixed Subjects Design
Social science experiments are chronically underpowered because human data is expensive. Large language models can cheaply predict human responses — but treating those predictions as substitutes for people (“silicon sampling”) produces confidently wrong conclusions. The mixed-subjects design charts the middle path: keep humans as the gold standard, treat LLM predictions as potentially informative observations, and combine them so that estimates get cheaper and more precise while remaining unbiased no matter how wrong the model is. As AI improves, the same designs automatically get better. I co-developed the design and lead its extension into causal inference, psychometrics, and shared research infrastructure.
“[I]t's the most reasonable approach I've seen in the LLMs for social science literature for integrating LLM simulations into confirmatory-style experiments…”
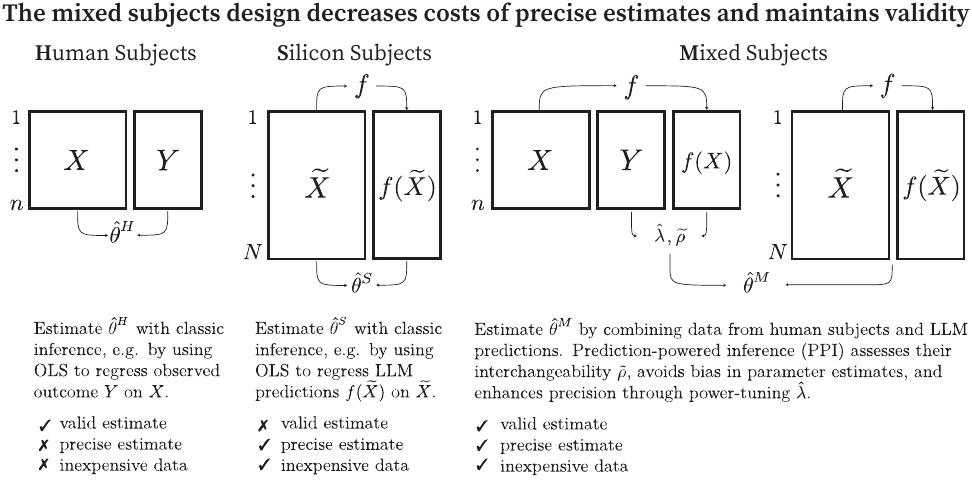
The Mixed Subjects Design: Treating large language models as potentially informative observations
PublishedDavid Broska, Michael Howes & Austin van Loon · Sociological Methods & Research, 2025
The paper that introduced the design. Using prediction-powered inference, it shows how to combine a smaller human benchmark with abundant LLM predictions, contributes the PPI correlation (a measure of how informative predictions are) and a matching power analysis, and demonstrates the stakes by reanalyzing over a million Moral Machine decisions: silicon-only sampling produced biases as large as 363% of an effect, while mixed-subjects estimates stayed unbiased with correct confidence-interval coverage.
Integrating generative artificial intelligence into experimental social science without compromising validity
Working paperAustin van Loon & Klint Kanopka
This paper puts mixed-subjects randomized experiments on formal footing in the potential-outcomes framework, introducing a family of estimators — several of them new — that are unbiased in finite samples regardless of prediction quality. Reanalyzing 195 treatment effects from prior experiments, we find LLM predictions cut fielding costs by around 6% when models see only demographics, and by more than 60% when they see participants' past behavior. The framework is implemented in our R package,
mixedsubjects. (Draft available on request.)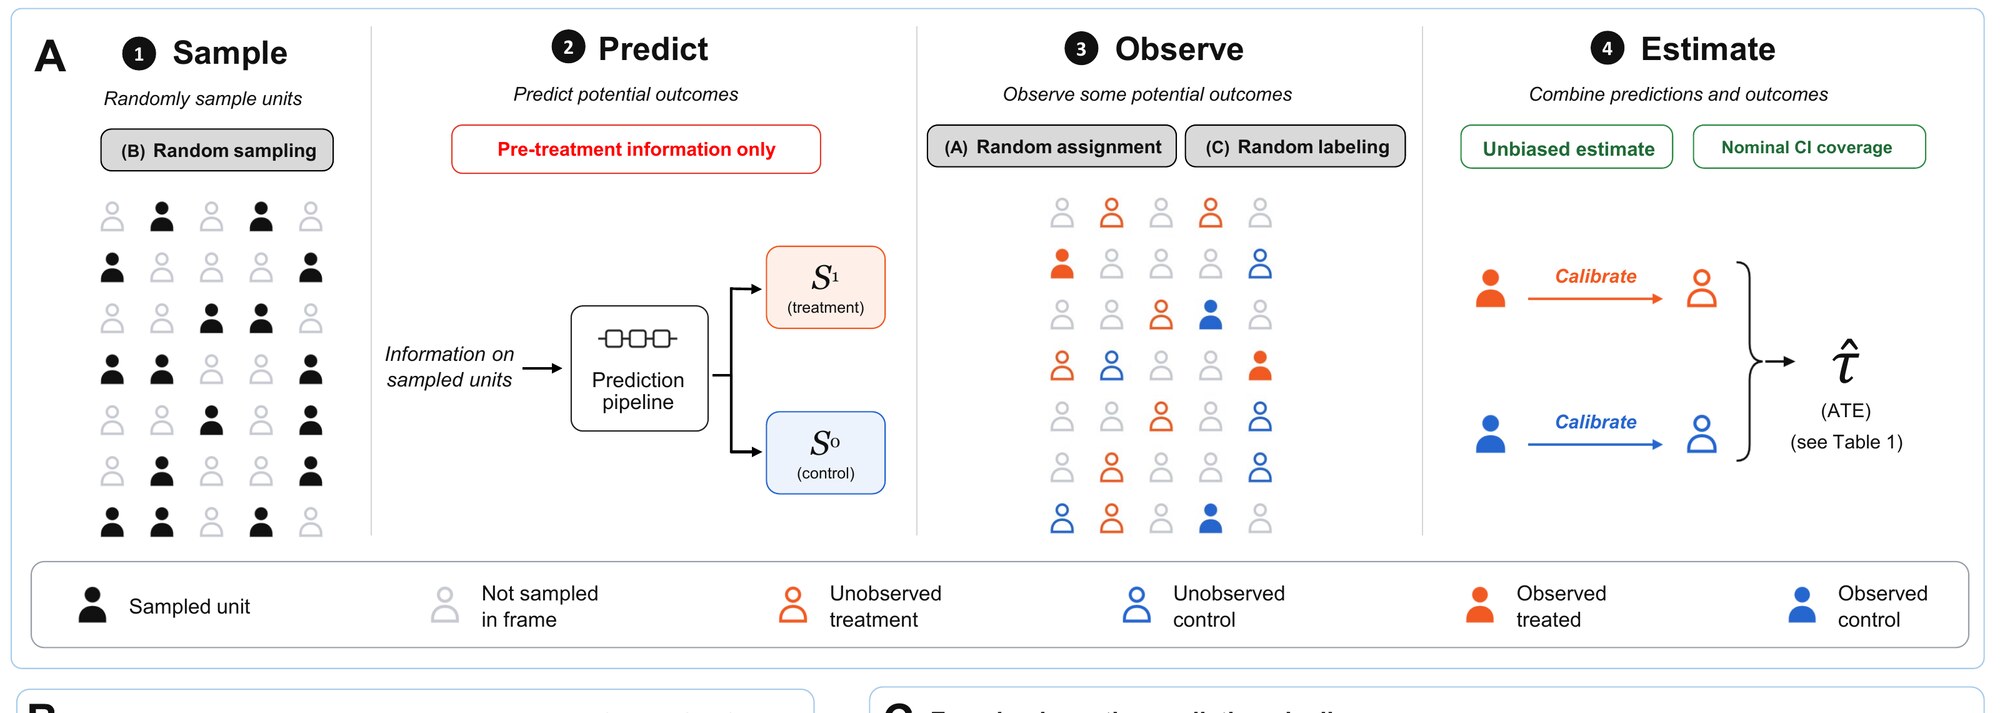
The mixed-subjects RCT workflow: sample, predict, observe, estimate. Austin van Loon & Zoe Heidenry · Nature Computational Science, 2025 · invited News & Views
An invited commentary on large-scale “silicon replications”: LLMs reproduce a striking share of published experimental effects, but inflate effect sizes, compress behavioral variability, and stumble on studies involving race and gender — reasons to treat AI simulations as objects of study rather than substitutes for human data.
Ongoing in this project:
- There are many open questions about expanding the causal inference framework for mixed subjects designs. We are working on latent variable estimation and matrix completion now, but we are also interested in inference under confounding (treatment assignment and labeling), adaptive designs, and Bayesian formulations.
- With Jeremy Freese, Klint Kanopka, and David Broska, I am working to explore how mixed subjects design experiments can be implemented at scale with new research infrastructure at the lab and national levels.
- The use of digital twins in experimental social science raises many ethical questions. Our team is also developing governance frameworks now, because these principles should influence the infrastructure before it is online.
- Part of improving returns in mixed subjects design experiments is increasing the accuracy of digital twin predictions. To further this, we are exploring several approaches, including ways to explore the space of possible prompting templates.
Software: the mixedsubjects R package implements the full estimator family plus tools for optimally splitting a budget between human and silicon subjects. See the Software & Teaching page →
What Does Text Analysis Actually Measure?
Computational text analysis lets social scientists measure ideology, emotion, and cultural meaning at scale — but a fundamental question often goes unasked: are these methods measuring what we think they are? This project builds the validity foundations for text-as-data research, including some uncomfortable demonstrations of what happens when we skip that step.
Austin van Loon · Social Science Research, 2022
Written for the journal's 50th-anniversary special issue, this solo-authored review organizes automated text analysis into three families — term frequency, document structure, and semantic similarity — based on the linguistic features each extracts, and shows how each family connects (or fails to connect) to the constructs social theories care about.
Austin van Loon & Jeremy Freese · American Behavioral Scientist, 2023 · lead article
Do embeddings capture culturally shared meanings? Machine learning models applied to word embeddings recover survey-measured affective meanings of concepts — how good, powerful, and active a “mother” or a “cop” is — with out-of-sample correlations approaching 0.9 for evaluation and above 0.7 for potency and activity, including pre-registered predictions for 257 never-before-rated concepts. Fundamental sentiments are encoded in everyday language, and can now be measured at near-zero marginal cost.
Austin van Loon , Salvatore Giorgi, Robb Willer & Johannes Eichstaedt · ICWSM, 2022
A cautionary tale. Embedding-based measures of regional anti-Black bias, computed from over a billion tweets, correlate with implicit bias, racial resentment, and segregation — until you control for a single variable: how often Black names appear in each region's corpus. Every correlation vanishes. Embeddings conflate frequency with meaning, and standard controls won't save you.
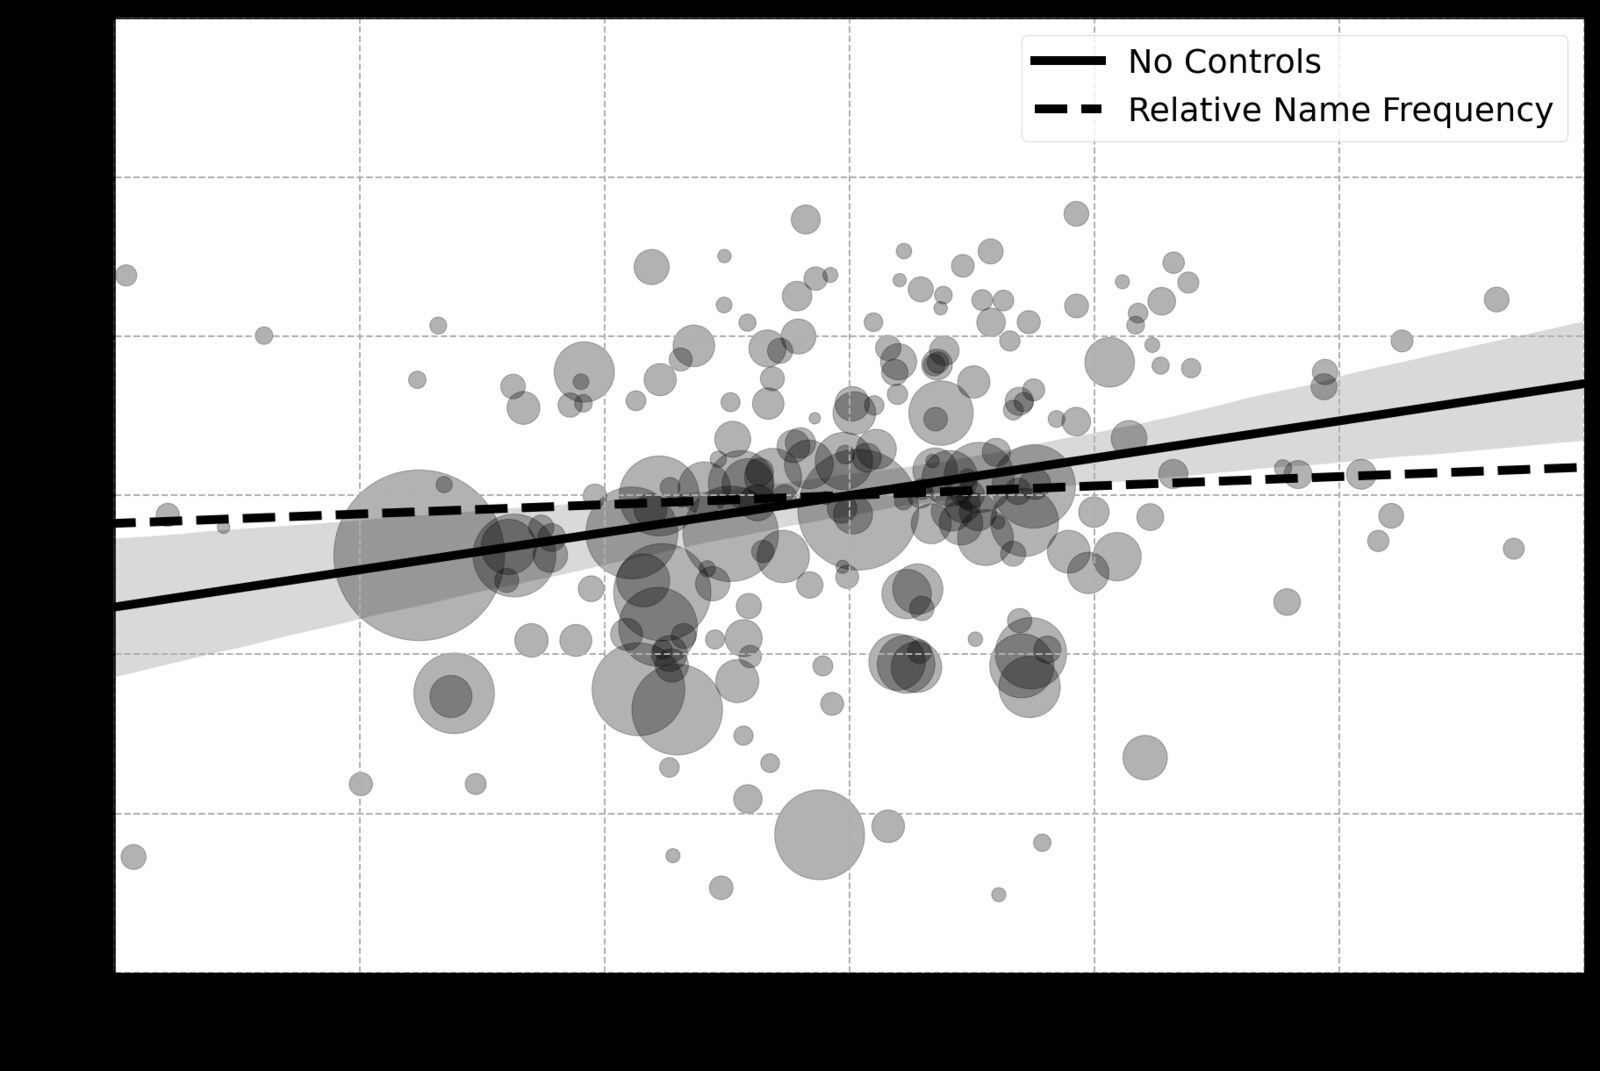
The apparent link between embedding-measured bias and implicit bias (solid line) vanishes once relative name frequency is controlled (dashed line). Austin van Loon · The Oxford Handbook of the Sociology of Machine Learning (Oxford University Press), 2025
Machine learning and theory-testing are often cast as rivals. This chapter argues that many important social theories are predictability hypotheses — claims that one construct predicts another, without specifying how — and that ML's flexible estimators are precisely the right tool for testing them within the classical hypothetico-deductive model.
Textual embeddedness: Towards mechanistic-based explanations with computational text analysis
Working paperMiriam Hurtado Bodell & Austin van Loon
Text analysis is good at describing cultural change and bad at explaining it. We develop textual embeddedness — the principle that texts are traces of socially situated communicative action — and show how it connects text-as-data research to mechanism-based explanation, a point that matters more, not less, in the era of large language models.
Ongoing in this project: Unnatural Language Understanding — we experimentally manipulate text corpora so that artificial tokens have known, legible properties, then test whether embeddings and topic models actually recover those properties in their representations. Early results suggest popular methods measure different things for frequent versus rare words.
Large-scale collaborations
I have also contributed to two landmark scientific mass collaborations:
- Measuring the predictability of life outcomes with a scientific mass collaboration (PNAS, 2020) — as one of 160 teams in the Fragile Families Challenge, which found that even the best machine-learning models, given 15 years of rich data, barely beat a simple four-variable benchmark at predicting life outcomes.
- Insights into the accuracy of social scientists' forecasts of societal change (Nature Human Behaviour, 2023) — as a member of the Forecasting Collaborative, whose tournaments showed that social scientists' forecasts of societal change were, on average, no more accurate than simple statistical baselines.